
Environmental protection and energy sustainability have become central issues in the modern automotive industry. In recent years, the deployment of electric vehicles has accelerated worldwide because they can significantly reduce greenhouse gas emissions from the transportation sector. As the core energy storage component of electric vehicles, the vehicle traction battery directly determines driving range, safety performance and overall lifetime cost. However, the performance of the vehicle traction battery inevitably degrades with repeated cycling, causing capacity fade, impedance rise and an increasing risk of thermal runaway. Therefore, accurately predicting the health information of the vehicle traction battery, such as the current remaining cycle count, state-of-health (SOH), state-of-charge (SOC) and remaining useful life (RUL), is a critical task for reliable battery management systems.
Traditional approaches for battery health prediction can be divided into model-driven and data-driven methods. Model-driven methods rely on electrochemical models or equivalent circuit models, which require deep understanding of internal chemical reactions and often demand high computational resources. Even sophisticated models may fail to capture all degradation mechanisms because batteries undergo complicated multi-factor aging processes. In contrast, data-driven approaches build the predictive model purely from measured data, without assuming explicit chemical or electrical equations. With advances in machine learning, these approaches have become flexible, fast and increasingly accurate for practical vehicle traction battery management.
This paper presents a comprehensive study on applying machine learning algorithms to predict the health information of vehicle traction batteries. In particular, I first discuss important steps in building a reliable prediction model, including feature collection, feature importance assessment, data cleaning, preprocessing, algorithm selection and hyper-parameter tuning. Then I evaluate several machine learning models on a common battery dataset and compare their prediction accuracy. Finally, I propose a hybrid framework that integrates a neural network with Gradient Boosting Decision Tree (GBDT) to further improve prediction performance. I demonstrate that this hybrid framework reduces the mean absolute error by more than 41% compared with a strong CatBoost baseline, and I verify its generalization on additional battery degradation datasets.
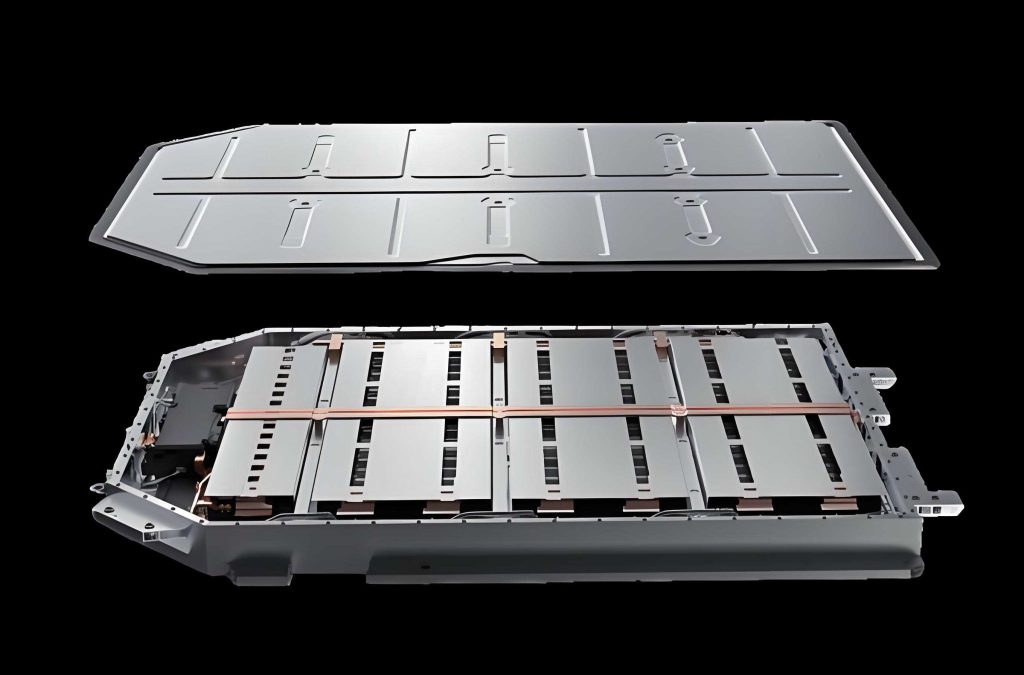
1. Problem Formulation and Modelling Methodology
1.1 Dataset Descriptions
To build and evaluate machine learning models for vehicle traction battery health prediction, I used three open-source datasets with different chemistries, working protocols and measured parameters. In the main comparison study, I employed a large-scale commercial lithium-ion battery dataset consisting of 124 cells cycled until failure under fast charging conditions. The charging strategy included two constant-current steps with a constant-current/constant-voltage finishing stage, and all cells were discharged at a 4C rate. Each battery was considered dead when its capacity degraded to 80% of rated capacity. The measured variables include the maximum charging power, maximum discharging power, internal resistance, maximum temperature, average temperature, minimum temperature, charging time and the instantaneous discharge power profile of each cycle. The target variable is the current cycle number of the cell, which directly reflects the health status. For the generality test, I also used an aerospace battery dataset and an automotive battery degradation dataset. The former provides impedance-related parameters while the latter provides ordinary charging/discharging voltage and temperature profiles.
1.2 Feature Importance Evaluation
Feature engineering is the cornerstone of employing machine learning for vehicle traction battery health prediction. In many practical applications, hundreds of candidate features can be computed from raw battery measurements, but some features are noisy, redundant or expensive to obtain. I considered three main criteria to choose features: acquisition difficulty, coverage and accuracy. Features with low acquisition difficulty and high coverage are preferred because they are easy to measure and represent a wide range of operating conditions. In addition, I need to know the relative importance of each candidate feature with respect to the target variable.
Feature importance can be evaluated in many ways. The simplest way is to inspect the correlation between input and output values. If an input variable hardly changes while the output changes substantially, it cannot be a critical predictor. More advanced methods use machine learning models themselves. For example, one can train a model on different subsets of features and compare accuracy to determine importance. Another popular method analyses the trained tree structure: when a feature is not selected as a split in most trees, its contribution is small.
Here I used a random forest model because it gives a practical intrinsic score for each feature. The detailed procedure is summarized as follows:
- Choose a set of battery parameters that are available from the first cycling dataset: maximum charging power $Q_d$, maximum discharging power $Q_c$, internal resistance $IR$, charging time $t_{ch}$, average temperature $T_{avg}$, maximum temperature $T_{max}$, and minimum temperature $T_{min}$.
- Train a random forest regressor with 200 trees on the whole shuffled dataset without tuning too carefully.
- Compute the impurity-based feature importance from all decision trees and normalize the scores.
I began with a subset of five features, namely $Q_d$, $Q_c$, $IR$, $t_{ch}$ and $T_{avg}$. The random forest importance results are shown in Table 1.
| Feature | Importance (with five features) |
|---|---|
| $Q_d$ (max discharge power) | 0.52 |
| $IR$ (internal resistance) | 0.22 |
| $t_{ch}$ (charging time) | 0.12 |
| $Q_c$ (max charge power) | 0.07 |
| $T_{avg}$ (average temperature) | 0.07 |
Although one may incorrectly conclude that average temperature is almost irrelevant, the story changes when I include $T_{max}$ in the feature set. Table 2 shows the importance ranking for six features.
| Feature | Importance (with six features) |
|---|---|
| $T_{max}$ (maximum temperature) | 0.387 |
| $t_{ch}$ (charging time) | 0.211 |
| $Q_d$ | 0.140 |
| $IR$ | 0.112 |
| $Q_c$ | 0.090 |
| $T_{avg}$ | 0.060 |
A central finding is that feature importance is not fixed; it depends on the whole set of candidate predictors. When I removed each one of the six features in turn and retrained the random forest, the ranking of the remaining features also changed. This is a well-known problem with impurity-based importance when features are correlated. Therefore, I cannot simply discard $IR$ based on a single five-feature experiment. Increasing the number of meaningful features generally improves the prediction accuracy, unless the newly added feature has little relevance or introduces too much noise.
1.3 Data Preprocessing
Data preprocessing is essential for constructing robust vehicle traction battery health prediction models. In the first dataset, each battery cell produces a summary record for each cycle, including several scalar values and a time-series profile of instantaneous discharge power. The target cycle number ranges from 1 to more than 1800, and the distribution spans different charging policies. Before using the data, I performed the following operations:
- Outlier detection: I removed samples with physically impossible values such as negative temperatures or zero capacity.
- Feature cleaning: If a feature contains a large number of NaN values, I either filled the missing values by linear interpolation or dropped that feature.
- Target filtering: Because early-cycle predictions are less important in practice, I sometimes discarded the first 10–85 cycles to avoid the extremely low target region that caused large relative errors.
- Data shuffling: All remaining samples were shuffled randomly to remove ordering effects, since many algorithms assume independent samples.
- Scaling: For neural networks, each input feature was standardized to zero mean and unit variance.
For neural network training, I also augmented the scalar features with the time-series discharge power profile of length 1000. This profile was normalized independently. The model used mini-batch training so I constructed PyTorch datasets that output tensors of shape (batch_size, 7) for the scalar features and (batch_size, 1000) for the time-series feature.
1.4 Machine Learning Algorithms
In this work I selected six different machine learning predictive algorithms to compare their suitability for vehicle traction battery health prediction:
- Random Forest (RF): an ensemble of decision trees grown in parallel, not sensitive to hyperparameters but may overfit in noisy regression tasks.
- XGBoost: an optimized gradient boosting system that handles sparse data and uses regularization.
- LightGBM: a fast and memory-efficient gradient boosting framework that uses leaf-wise tree growth.
- CatBoost: a gradient boosting library that handles categorical features internally and applies ordered boosting to reduce overfitting. It has demonstrated high performance on structured data.
- Neural Network (DNN / LSTM): a deep learning approach that captures complex nonlinear relationships and can flexibly combine different input formats.
- Hidden Markov Model (HMM): a Bayesian probability sequence model.
The goal of every model is to predict the battery current cycle number (or remaining useful cycle) as a regression output. The loss function for training was mean squared error because I wanted to minimize large deviations.
1.5 Hyper-parameter Tuning with a Chaotic Sparrow Algorithm
Machine learning algorithms usually contain hyperparameters that must be configured before training. For different vehicle traction battery datasets, the optimal hyperparameters can vary significantly. Manual tuning is time-consuming and may produce poor solutions. In my early experiments, I used the validation-set error to guide a chaotic sparrow search algorithm (CSSA) to find good hyperparameters quickly. The sparrow search algorithm mimics the foraging and anti-predation behaviours of sparrow groups. Its main update equations are:
Scout (producer) update strategy:
$$x_{i,d}^{t+1} = \begin{cases}
x_{i,d}^{t} \cdot (1+Q), & R_2 < ST \\
x_{i,d}^{t} + Q, & R_2 \ge ST
\end{cases}$$
where $x_{i,d}^{t}$ is the position of the $i$-th individual in dimension $d$ at iteration $t$, $Q$ is a random number drawn from the standard normal distribution, $R_2$ is a random number in $[0,1]$, and $ST$ is a warning threshold in $[0.5,1]$.
Follower update strategy:
$$x_{i,d}^{t+1} = xb_{i,d}^{t} + \frac{1}{D}\sum_{d=1}^{D} \text{rand}(-1,1) \cdot (xb_{i,d}^{t} – x_{i,d}^{t})$$
where $xb$ represents the best position in the current population.
Anti-predation behaviour:
$$x_{i,d}^{t+1} = \begin{cases}
x_{i,d}^{t} + \beta (x_{i,d}^{t} – xb_{i,d}^{t}), & f_i \neq f_g \\
x_{i,d}^{t} + \beta (xw_{i,d}^{t} – xb_{i,d}^{t}), & f_i = f_g
\end{cases}$$
To escape from local optima, the chaotic sparrow algorithm additionally performs Gaussian mutation for individuals with below-average fitness:
$$\text{mutation}(x) = x (1 + N(0,1))$$
and Tent chaotic perturbation for the remainder. The improved Tent map is given by:
$$z_{i+1} = 2 z_i \bmod 1 + \text{rand}(0,1)\cdot\frac{1}{N_T}$$
where $N_T$ is the number of chaotic particles. These enhancement mechanisms enhance the global search ability and help find a better hyperparameter configuration for a given battery dataset.
2. Baseline Prediction Results on the Vehicle Traction Battery Dataset
2.1 Experimental Setup
All baseline models were evaluated on the same primary battery dataset. I selected six scalar input features: $Q_d$, $Q_c$, $IR$, $T_{max}$, $T_{avg}$, $t_{ch}$. At first, I also tried five features without $T_{min}$. After comparing different subsets, I found that using six features improved the prediction accuracy. Some experiments used seven scalar features (including $T_{min}$) as described later. The output is always the cycle number.
I divided the dataset into training and test sets using a ratio of 90% to 10%, and I shuffled all samples. For the neural network, I additionally divided the training set into training and validation partitions during tuning, but after tuning I retrained on the full training split. Hyperparameters were selected either empirically or by the chaotic sparrow search algorithm. Table 3 lists examples of hyperparameters used for the four ensemble algorithms.
| Algorithm | Hyperparameter | Value |
|---|---|---|
| Random Forest | n_estimators | 200 |
| XGBoost | learning_rate, max_depth, lambda | 0.063, 10, 1 |
| LightGBM | learning_rate, max_depth, num_leaves | 0.3, 5, 21 |
| CatBoost | iterations, depth, learning_rate | 28000, 12, 0.02 |
2.2 Ensemble Learning Results
After training each ensemble model on the training set, I evaluated its performance on the test set. I computed three error metrics: mean absolute error MAE, mean squared error MSE, and the proportion of predictions whose relative absolute error falls into certain intervals. The definitions of the metrics are:
$$\mathrm{MAE} = \frac{1}{N}\sum_{i=1}^{N} |y_i-\hat{y}_i|$$
$$\mathrm{MSE} = \frac{1}{N}\sum_{i=1}^{N} (y_i-\hat{y}_i)^2$$
$$\mathrm{Relative\ error} = \frac{|y_i-\hat{y}_i|}{y_i} \times 100\%$$
Table 4 summarizes the average errors for all four ensemble algorithms. The test set contained 11470 samples with an average value of 488 cycles.
| Algorithm | MAE | MSE | >20% errors | 10%–20% errors | <10% errors |
|---|---|---|---|---|---|
| Random Forest | 22.20 | 3375.61 | 10.75% | 7.94% | 81.31% |
| XGBoost | 27.66 | 3447.43 | 12.89% | 11.00% | 76.11% |
| LightGBM | 31.53 | 3933.45 | 15.30% | 12.98% | 71.72% |
| CatBoost | 25.43 | 2926.77 | 11.87% | 11.04% | 77.10% |
Random forest achieved the lowest MAE of 22.20 and the highest proportion of predictions with relative error below 10%. CatBoost produced a slightly higher MAE but a distinctly lower MSE than Random Forest, implying it avoids very large outliers better. LightGBM, in terms of average relative error on those large-error points, performed best, because its extreme predictions were not as far off as those of other models. Overall, both Random Forest and CatBoost are strong candidates.
One major source of large relative errors was the small true cycle values. For instance, when the true cycle number is below 10, even an absolute error of a few cycles produces a relative error of hundreds of percent. In real vehicle traction battery management, we rarely need to predict the remaining life for a battery that will last only 10 cycles, and the very first cycles contain many transient effects. Therefore, I filtered out test and training samples with true cycle numbers below 85 to evaluate the performance in a practically meaningful region. Table 5 shows the results after filtering.
| Algorithm | MAE | MSE | >20% gaps | 10–20% | <10% |
|---|---|---|---|---|---|
| Random Forest | 21.81 | 3354.76 | 6.7% | 7.15% | 86.14% |
| XGBoost | 27.60 | 3490.52 | 7.81% | 10.44% | 81.75% |
| LightGBM | 31.50 | 3985.01 | 9.59% | 12.92% | 77.50% |
| CatBoost | 25.33 | 2957.23 | 6.77% | 10.32% | 82.90% |
The proportion of samples with relative error greater than 20% decreased noticeably, confirming that low-cycle samples contributed most of the large relative errors. However, the absolute errors were not reduced substantially. To improve the model further, I attempted to increase the feature count from five to six by adding $T_{max}$.
In each comparison, I discarded samples below cycle 85, giving a test set size of 10318 samples with an average output of 537.64. I then trained CatBoost using the following three input configurations: (i) without $IR$ (five features: $Q_d,Q_c,T_{max},t_{ch},T_{avg}$), (ii) with six features ($Q_d,Q_c,IR,T_{max},t_{ch},T_{avg}$) and (iii) without $T_{avg}$ (five features: $Q_d,Q_c,IR,T_{max},t_{ch}$). The results are shown in Table 6.
| Configuration | MAE | MSE | >20% | 10–20% | <10% |
|---|---|---|---|---|---|
| Five features without $IR$ | 34.39 | 4602.80 | 11.44% | 13.79% | 74.77% |
| Six features | 18.60 | 1787 | 4.66% | 6.9% | 88.44% |
| Five features without $T_{avg}$ | 24.12 | 2781.88 | 6.33% | 8.92% | 84.74% |
Simply removing $IR$ — even though it appeared least important in one importance analysis — worsened the result dramatically. This again emphasizes the contextual nature of feature importance. Adding $T_{max}$ to the original five features provided a considerable improvement: MAE dropped from about 25.33 to 18.60, and MSE nearly halved. Therefore, meaningful new information is more valuable than maintaining a small feature set.
2.3 Error Analysis for the Best Ensemble Model
To analyse the remaining unpredictable cases, I divided the filtered test set into three groups according to the relative cycle position, i.e. the current cycle divided by the battery total life. I inspected the samples were predicted with relative error greater than 20%. Table 7 shows the absolute counts and proportions.
| Relative cycle range | Number with >20% error | Total samples | Percentage |
|---|---|---|---|
| >0.8 | 107 | 2351 | 4.55% |
| 0.2–0.8 | 284 | 6872 | 4.13% |
| <0.2 | 91 | 1112 | 8.18% |
Although the average accuracy is acceptable in all phases, there are still a few outliers with unacceptably large absolute deviations. For practical vehicle traction battery health monitoring, one can mitigate this issue by predicting the remaining life using a sliding window on multiple consecutive cycles and taking the median or average of the predictions, which removes transient noise.
2.4 Neural Network Results
Neural networks have emerged as powerful tools for vehicle traction battery health prediction. Their main advantage is the flexibility to consume multiple formats of input features simultaneously. In this section I built a DNN and a DNN-LSTM hybrid network. The DNN receives the scalar features, and the LSTM branch processes the time-series discharge-power profile recorded during each cycle.
The architecture contains the following layers:
- Input layer: 7 scalar features (normalized) for the DNN branch; 1000 time steps with one input channel for the LSTM branch.
- DNN branch: BatchNorm1d -> Linear(7, 256) -> ELU -> Dropout(0.2) -> Linear(256, 32).
- LSTM branch: LSTM(1000, 64, hidden layers=1) -> Linear output to 32 neurons.
- Concatenate branch outputs: 64 features.
- Final DNN: Linear(64, 128) -> ELU -> Dropout(0.2) -> Linear(128, 1).
The activation function ELU is defined as:
$$\text{ELU}(x) = \begin{cases}
x, & x > 0 \\
\alpha (\exp(x)-1), & x \le 0
\end{cases}$$
Batch normalization is performed on each mini-batch of size $m$:
$$\mu_B = \frac{1}{m}\sum_{i=1}^{m} x_i, \quad \sigma_B^2 = \frac{1}{m}\sum_{i=1}^{m}(x_i-\mu_B)^2$$
$$\hat{x}_i = \frac{x_i-\mu_B}{\sqrt{\sigma_B^2+\epsilon}}, \quad y_i = \gamma \hat{x}_i + \beta$$
where $\gamma$ and $\beta$ are learnable parameters initialized to 1 and 0 respectively. The entire network was trained by minimizing the MSE between the predicted cycle number and the ground truth. I set batch size to 64, used the Adam optimizer with a learning rate of 0.001, and applied early stopping on a validation set.
For a fair comparison, I used the same training and test split as in the ensemble comparison. Table 8 shows the prediction errors for two neural network setups, alongside the HMM result which will be described in the next section. Here I used a test set with average value 484.26 and 22920 samples. The DNN-LSTM model receives one additional time-series feature, while the DNN only sees the 7 scalar features.
| Model | MSE | MAE |
|---|---|---|
| DNN (7 scalar inputs) | 12074.13 | 70.80 |
| DNN-LSTM (7 scalar + 1 time series) | 3863.29 | 43.07 |
| Hidden Markov Model (HMM, supervised) | 86396.39 | 213.59 |
The performance of DNN was significantly worse than CatBoost (MAE = 19.49). However, adding the time-series discharge profile with an LSTM branch reduced both MSE and MAE substantially. This demonstrates that when richer, carefully structured information is provided to the neural network, the model benefits from the hidden patterns in the time series.
2.5 Bayesian Probability Method
To broaden the perspective of data-driven methods, I also investigated the Hidden Markov Model, a Bayesian probabilistic sequence approach. In this case, HMM was used to model the observable variables (features) and an unobservable discrete state that represents the battery health level. In an unsupervised setting, the HMM can predict future feature observations after learning from a sequence of 20 past cycles. The predicted features closely tracked the real trends for $Q_d$, $Q_c$, $IR$, $T_{avg}$ and $t_{ch}$, and the cycle number could be inferred from the predicted hidden state. The disadvantage is that each HMM is trained individually on one subset, so it cannot fit a large general dataset as conveniently as tree-family models.
In a supervised setting, I pre-discretized both features and target into levels. The target (cycle number) was divided into bins of 100 cycles. Then I trained the HMM on labeled sequence data, where emissions are discrete observation indices. Table 9 shows the average prediction errors of 46 supervised HMM models. Each model was tested on 100 unseen sequences, and the average error is reported in the first column. The second column indicates the error interval range over trials.
| HMM trial | MAE | Error interval | Max cycle |
|---|---|---|---|
| Example 1 | 0.16 | [0.16,115] | 690 |
| Example 2 | 0.17 | [0.17,116] | 533 |
| … | … | … | … |
| Example 46 | 1.34 | [72.62,233] | 1225 |
These results are difficult to compare with regression models because the output is a bin index rather than a continuous cycle. However, the supervised HMM achieves a relatively high sequence prediction accuracy and consumes a fair amount of preprocessing time. The model performance depends heavily on the quality of discretization and the number of hidden states. HMM can be useful for smooth degradation sequences but is not as convenient as supervised regression learners for large vehicle traction battery datasets.
3. Hybrid DNN-LSTM and CatBoost Fusion Model
3.1 Motivation
CatBoost is a gradient boosting algorithm based on oblivious decision trees. It has consistently shown excellent predictive power on structured tabular data. Its strength lies in the robust construction of an additive ensemble of weak learners. A well-trained CatBoost model partitions the input feature space into many constant-valued leaf regions. However, CatBoost cannot directly accept a long time-series profile such as the 1000-point discharge curve, unless it is manually compressed into a handful of hand-crafted summary statistics. In contrast, neural networks, especially LSTMs, are natural tools to encode temporal information. Therefore, it is reasonable to combine the two paradigms in a hybrid framework to let the neural network convert time-series features into informative latent vectors, which can then be fed into CatBoost together with the original scalar features.
I call this architecture the DNN-LSTM-CatBoost fusion model. The overall modelling procedure is illustrated in Figure (not shown here) and is straightforward:
- Train a DNN-LSTM neural network on the original inputs with the target being the battery current cycle number.
- Remove the final output layer from the trained network. Take the inputs to the last fully connected layer (8 neurons) as new features. For every sample from the original training set and test set, forward propagate it through the network up to this layer to obtain 8 new continuous features.
- Add these 8 new features to the original scalar features (e.g. 7 features), resulting in 15 features for each sample.
- Train a CatBoost model on the augmented feature matrix.
- Use the test-time new features from the same neural network to make predictions with the CatBoost model.
Table 10 defines the three comparison cases on the primary vehicle traction battery dataset. All cases use the same 8:2 train-test split, producing 91678 training samples and 22920 test samples. The target output is always the cycle number.
| Case | Training input dimensions | Test input dimensions | Trained model |
|---|---|---|---|
| Case 1 | 91678 × 7 | 22920 × 7 | DNN |
| Case 2 | 91678 × 1007 | 22920 × 1007 | DNN-LSTM |
| Case 3 | 91678 × 7 | 22920 × 7 | CatBoost |
Case 1 is a plain DNN receiving only scalar features. Case 2 uses the same scalar features plus the time-series of 1000 discharge-power values. Case 3 uses CatBoost with the same scalar features that Case 1 receives. The MSE and MAE results are reported in Table 11.
| Case | MSE | MAE |
|---|---|---|
| Case 1: DNN | 12074.13 | 70.80 |
| Case 2: DNN-LSTM | 3863.29 | 43.07 |
| Case 3: CatBoost | 1525.03 | 19.49 |
CatBoost outperforms both neural networks even though it sees fewer input dimensions. This is not surprising because GBDT-style models usually excel on tabular data with moderate sample sizes. However, the DNN-LSTM successfully encodes the long time-series feature into latent representations that CatBoost cannot directly see. The fusion model combines strengths and achieves a significant improvement, as shown in Table 12.
| Model | MSE | MAE | Relative error <5% | Relative error 5–20% | Relative error >20% |
|---|---|---|---|---|---|
| DNN-LSTM-CatBoost fusion | 641.44 | 11.50 | 78.85% | 16.82% | 4.33% |
Compared to Case 3’s MAE of 19.49, the fusion model reduces MAE by 41%. Even compared with the excellent DNN-LSTM neural network, the reduction is large. This demonstrates that adding neural-network-derived features, even if they are abstract and lack physical meanings, provides useful inductive bias for the tree-based model.
3.2 Why Do the Neural Network Features Help?
To verify that the eight extracted latent features actually carry information, I designed a control experiment, named Case 4. Starting from the original features, I replaced the eight neural-network-derived features with independent random numbers sampled from a standard normal distribution. Then I trained CatBoost on (7+8) features where the last eight are pure noise. Table 13 shows the training RMSE and test MSE for CatBoost with genuine latent features (Case 5) versus CatBoost with random noise (Case 4).
| Training round | Case 3 train RMSE | Case 4 (random features) train RMSE | Case 3 test MSE | Case 4 test MSE |
|---|---|---|---|---|
| Round 1 | 366.86 | 366.79 | – | – |
| Round 75 | 168.27 | 168.70 | – | – |
| … | … | … | – | – |
| Round 11925 | 17.60 | 10.02 | – | – |
| Round 12000 | 17.52 | 9.94 | 641.44 | 1352.30 |
The random-noise version reaches a much lower training RMSE because CatBoost easily overfits the meaningless noise dimensions to fit the training targets. In contrast, the genuine latent features do not allow CatBoost to overfit so aggressively and they substantially reduce the test MSE. This confirms that the extracted features are informative and meaningful.
3.3 Generalization to Other Vehicle Traction Battery Datasets
A crucial requirement is that the fusion method should not be a special coincidence tailored for one specific vehicle traction battery dataset. Therefore, I tested the same methodology on two additional public battery degradation datasets using the corresponding neural network structures and data preprocessing strategies.
For the second dataset, I used two scalar features from impedance measurements and an additional sequence of six-dimensional impedance measurements over 48 frequencys. A small CNN branch was employed to extract the time-series feature. For the third dataset, I used two types of features: one was a set of four scalar features, and the other was two separate long profiles of charging and discharging voltage over 1000 steps. Two LSTM branches (one per profile) were built. In each dataset, I trained a base CatBoost model using only the scalar features, and a fusion model in which the scalar features are concatenated with eight latent features extracted from the trained neural network. Table 14 gives the exact input formats and models.
| Dataset | Base CatBoost input dimension | Neural network type | Fusion CatBoost input dimension | Output dimension |
|---|---|---|---|---|
| Dataset II | 709×2 | DNN + CNN | 709×(2+8) | 709×1 |
| Dataset III | 414×4 | DNN + LSTM + LSTM | 414×(4+8) | 414×1 |
The test errors for these additional datasets are shown in Table 15. For Dataset II the test-set average is 92.25 cycles; for Dataset III it is 3528.85 cycles.
| Dataset | Model | MSE | MAE |
|---|---|---|---|
| Dataset II | DNN+CNN | 318.31 | 14.04 |
| CatBoost (scalar only) | 730.81 | 17.77 | |
| Fusion | 162.65 | 9.49 | |
| Dataset III | DNN+LSTM+LSTM | 70354.51 | 198.75 |
| CatBoost (scalar only) | 64814.20 | 140.50 | |
| Fusion | 33783.78 | 138.36 |
The fusion model consistently improves the CatBoost-only result on both additional datasets. In Dataset II, MAE drops from 17.77 to 9.49, an improvement of about 47%. In Dataset III, MAE drops only slightly from 140.50 to 138.36, while the MSE reduces almost by half, indicating that the fusion model suppresses severe outliers. These findings confirm that the proposed hybrid method generalizes well across different vehicle traction battery degradation datasets.
I also tested a variant in which the neural network uses exactly the same scalar features as CatBoost, and then I extract the eight new features from that neural network and feed them together with the original scalar features into CatBoost. Table 16 compares CatBoost trained on the original scalar inputs (Case base) versus CatBoost trained on the original scalar inputs plus eight features extracted from a neural network that eats the same scalar inputs. The results from the first, second and third datasets are shown.
| Dataset | CatBoost (base) MAE | CatBoost with latent features MAE | Dataset average |
|---|---|---|---|
| Dataset I | 19.49 | 17.32 | 484.26 |
| Dataset II | 17.77 | 19.10 | 92.25 |
| Dataset III | 140.50 | 97.57 | 3528.85 |
In two of the three datasets, adding latent features even from the same input information improves CatBoost. In the second dataset, the latent features slightly hurt performance, but when they are extracted from a richer model that includes the time-series CNN features, the fusion model still gives a large positive gain. This observation suggests that the latent features are not merely a duplicate of the original information; they capture non-linear interactions and transformed representations learned by the neural network. These representations help the gradient-boosted trees to partition the feature space in a more effective way.
3.4 Comparison with Related Studies
Table 17 compares the performance of several reported machine learning approaches for vehicle traction battery health prediction. It is important to note that different works use different datasets and train-test splits, so the error values are not directly comparable across datasets. Nevertheless, the table illustrates the range of reported errors and the improvement capability of hybrid methods.
| Reference | Algorithm | MAE / RMSE |
|---|---|---|
| Study A | LM-GPR | MAE 0.0136 (module 1) |
| Study A | Proposed hybrid | MAE 0.0126 (module 1) |
| Study B | CEEMD+LSTM | MAE 0.01273 |
| Study B | Proposed method | MAE 0.00659 |
| Study C | LSTM | MAE 1.8 |
| Study C | Proposed method | MAE 1.7 |
| This work | DNN | MAE 70.8 |
| This work | DNN-LSTM | MAE 43.07 |
| This work | CatBoost | MAE 19.49 |
| This work | Fusion | MAE 11.50 |
The proposed fusion model is therefore a practical way to integrate two complementary model families. It does not require inventing a completely new learning algorithm, but instead uses existing high-performance tools in an intelligent pipeline.
4. Discussion and Practical Insights
4.1 General Methodology for Data-Driven Vehicle Traction Battery Prediction
Through the extensive experiments in this paper, I have derived a general workflow for accurately predicting the health information of vehicle traction batteries using machine learning. The workflow begins with data acquisition, where the chosen parameters must cover physically meaningful quantities that are easy to obtain in real-time for vehicle traction battery management systems. Scalar statistics such as maximum charging power, maximum discharging power, internal resistance, charging time and average temperature already contain substantial health information. In addition, time-series profiles such as the discharging power or voltage trajectories can be recorded by modern battery management units.
The second step is feature engineering. It is recommended to use multiple sensors and capture both summary statistics and raw time-series waveforms. Feature importance evaluation should be performed carefully because the importance of each feature depends on the other features included. If the candidate pool is dozens, random forest importance can help eliminate irrelevant features. When the number is small, blindly deleting a feature that seems unimportant may harm prediction. A better strategy is to add informative features whenever possible.
The third step is preprocessing. For tree-based models, only light preprocessing such as missing-value handling and outlier removal is needed. For neural networks, standardization or normalization of inputs is mandatory, especially for features with different units and ranges such as internal resistance in ohms and temperature in Celsius.
The fourth step is algorithm selection. Based on this study, CatBoost is recommended for moderate-sized structured data because it achieved the best balance between speed and accuracy. Random Forest is also robust and simpler to tune. Deep learning models should be used when large volumes of data are available or when the inputs are high-dimensional sequences. In the latter case, LSTM/CNN branches should be used to extract fixed-length representations from time-series or image-like features.
The fifth step is hyper-parameter tuning. Instead of exhaustive grid search, an optimizer like the chaotic sparrow search algorithm can efficiently locate strong hyperparameters. The tuning process must use a separate validation set to avoid information leakage, and the final chosen hyperparameters should be re-evaluated on an untouched test set.
4.2 Benefits of the Proposed Fusion Model
The hybrid DNN-LSTM-CatBoost model is not limited to the specific NMC chemistry or the charging policy contained in this paper. The methodology can be applied to any vehicle traction battery dataset, as long as the training data are collected under the same cell design and testing policy. The neural network in the fusion model acts as a feature extractor, and the tree-based model remains the final regressor. This architecture has several advantages:
- It accepts scalar inputs and long sequences in their original formats without mandatory manual engineering.
- It leverages the excellent nonlinear representation ability of neural networks and the strong regularization properties of gradient boosting.
- It provides a clear and reproducible training pipeline that does not require altering the internals of either component.
- It can be extended to other ensemble algorithms such as Random Forest, XGBoost, or LightGBM, and also to Gaussian Process Regression or Support Vector Regression, possibly with similar benefits.
4.3 Limitations and Threats to Validity
One limitation of the proposed approach is its computational burden. Training a DNN-LSTM model is inherently slower than training a single CatBoost model. The extra cost is acceptable when one needs the highest possible accuracy for offline model building. Another limitation is caused by the data distribution. In my filtered datasets I sometimes removed low-cycle examples, which means the model is not intended to predict the first few cycles of a new battery. For real vehicle traction battery systems, one should retrain the model with a data collection that spans the entire lifecycle. Additionally, the eight extracted neural-network features are not physically interpretable. Even though they improve accuracy, field engineers may prefer simpler models. Future work should explore methods to explain these latent features or to extract physically meaningful health indicators (e.g., incremental capacity curves) and feed them into the same hybrid architecture.
5. Concluding Remarks and Future Work
In this paper I have systematically studied machine learning based prediction methods for vehicle traction battery health information, including feature engineering, preprocessing, base learners and model fusion. From the baseline comparisons, I concluded that CatBoost is a robust candidate for structured vehicle traction battery datasets. Random Forest is also competitive, while neural networks are less efficient on small tabular datasets but become useful when raw time-series information is integrated. I further designed a fusion framework that extracts latent representations from a trained DNN-LSTM and feeds them into CatBoost. The framework reduced MAE from 19.49 to 11.50 on the primary vehicle traction battery dataset, a 41% improvement, and consistently improved over CatBoost on two other independent datasets.
Another important lesson is that adding meaningful data can improve accuracy more than tuning a model. In the six-feature experiment, simply adding a maximum-temperature feature reduced MAE by more than 6 cycles, while removing internal resistance increased MAE by almost 15 cycles. Therefore, careful data engineering deserves more attention in future vehicle traction battery health prediction research.
Future research directions include: (1) applying the fusion framework with other neural network architectures such as temporal convolutional networks and graph neural networks; (2) using more advanced Bayesian optimization or reinforcement-learning based hyperparameter search to reduce the fusion model development time; (3) integrating uncertainty quantification so that the model not only outputs a point prediction but also a confidence interval, which is crucial for safety-critical vehicle traction battery systems; and (4) moving from current-cycle prediction to remaining-useful-life prediction with transfer learning across different battery types and operating environments.
In conclusion, the combination of flexible feature extraction from neural networks and powerful tabular learning from gradient boosted trees provides a promising direction for building accurate, reliable and practical vehicle traction battery health prediction tools. I believe that this methodology will benefit both academic research and industrial battery management system applications.