
1. Introduction and Research Context
In recent years, the push for carbon neutrality has accelerated the adoption of electric vehicles (EVs) globally. As an essential component of the EV battery pack, lithium-ion batteries directly affect the safety, performance, and lifespan of the vehicle. However, the battery pack’s performance degrades over time through repeated charge and discharge cycles, leading to capacity fade and increased internal resistance. When the State of Health (SOH) of an EV battery pack drops below 80%, it is typically considered end-of-life and must be replaced. Accurately predicting the health information of the EV battery pack, such as the State of Charge (SOC) and remaining useful life (RUL), is critical for battery management systems to ensure safe and reliable operation.
The methodology for predicting EV battery pack health can be divided into two categories: model-driven and data-driven. Model-driven approaches involve constructing equivalent circuit models or electrochemical models that simulate the physical and chemical processes within the battery. While these models offer physical interpretability, they are often computationally intensive to parametrize. Data-driven approaches, particularly those utilizing machine learning, have gained significant traction due to their ability to directly learn complex non-linear relationships from the measured data. In this thesis, I investigate various machine learning algorithms to predict the health information of EV battery packs, utilizing several public battery degradation datasets.
My research focuses on establishing a general methodology for EV battery pack health prediction using machine learning, comparing algorithms such as Random Forest, XGBoost, LightGBM, CatBoost, Neural Networks (DNN, LSTM), and Bayesian probability models. I also propose a novel fusion model that integrates neural networks and CatBoost to enhance prediction accuracy. Additionally, I employ the Chaotic Sparrow Search Algorithm (CSSA) for efficient hyperparameter optimization. This research aims to address key questions regarding dataset preprocessing, feature importance evaluation, and algorithm selection specifically tailored for the EV battery pack.
2. Data Description and Processing Methodology
To ensure a comprehensive analysis, I utilized three publicly available lithium-ion battery datasets. The primary dataset used throughout most of this research is the one published by Severson et al., which contains data from 124 commercial lithium-ion batteries cycled under fast charging conditions until failure, with failure defined as reaching 80% SOH. The data includes parameters such as maximum charge power (Qd), maximum discharge power (Qc), internal resistance (IR), maximum temperature (Tmax), average temperature (Tavg), minimum temperature (Tmin), and charge time (C_t). The second dataset is the NASA battery dataset, which provides impedance spectroscopy measurements over the battery’s lifetime. The third dataset is the Oxford battery degradation dataset, which contains cycling data from 8 cells under various conditions.
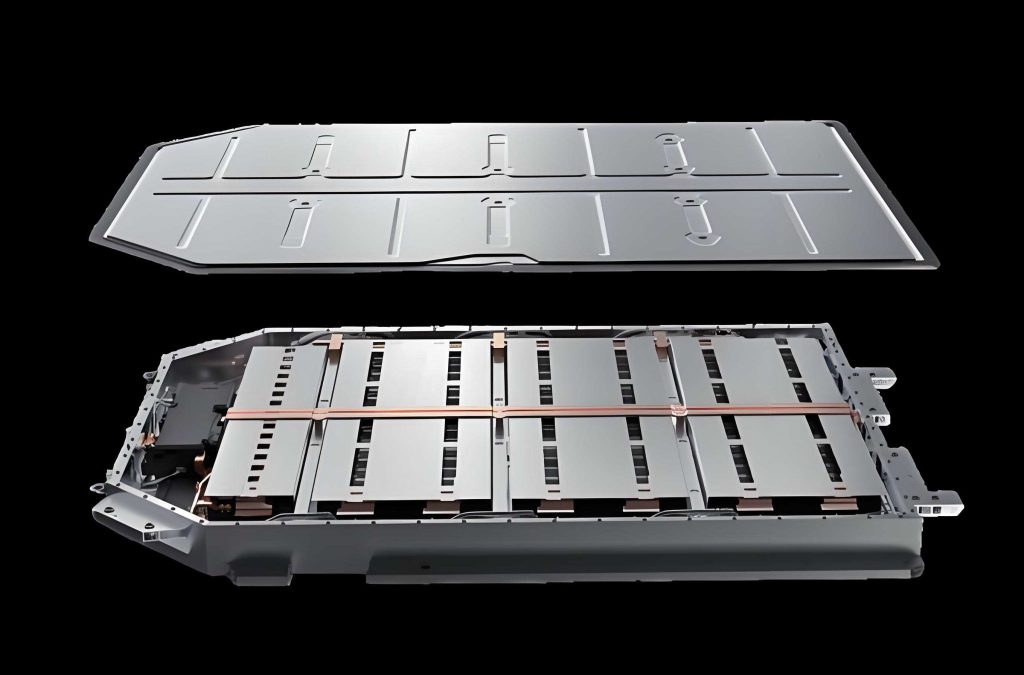
This image illustrates the complexity of modern EV battery pack systems, which consist of multiple cells, modules, and a sophisticated Battery Management System (BMS) that relies on accurate health predictions.
3. Methodology and General Framework
3.1 Feature Importance and Selection
In the realm of feature engineering, the usability of a feature can be evaluated using three primary indicators: acquisition difficulty, coverage rate, and accuracy rate. For predicting the health of an EV battery pack, I initially assessed the importance of the selected parameters using the Random Forest algorithm. This involved training a regression forest with 200 trees on datasets with different parameter combinations.
Table 3.1: Feature Importance Evaluation Results
| Parameter Group | Qd | Qc | IR | Tmax | Tavg | Tmin |
| :— | :— | :— | :— | :— | :— | :— |
| Five Parameters | 0.52 | 0.18 | 0.15 | – | 0.106 | – |
| Six Parameters | 0.187 | 0.117 | 0.1 | 0.387 | 0.1 | – |
The analysis revealed that when only five parameters are used, the maximum discharge power (Qd) has the highest importance. However, when the maximum temperature (Tmax) is added to create a six-parameter set, Tmax becomes the most dominant feature, underscoring that feature importance can change based on the inclusion of other informative variables.
3.2 Data Preprocessing
In the field of data preprocessing, several methods are crucial for preparing the raw data for machine learning algorithms. Standard practice includes handling missing values, feature scaling, and encoding categorical variables. In my analysis, I specifically focused on standardizing the input features to ensure the algorithms converge efficiently. The rationale behind the data preparation is that accurate prediction of the EV battery pack lifecycle serves as the ultimate validation of correct data processing.
3.3 Hyperparameter Optimization
Hyperparameter tuning is essential for a machine learning model to perform optimally. I investigated the use of a Chaotic Sparrow Search Algorithm (CSSA) to automate this process. The CSSA offers an advantage over the standard SSA by introducing Tent chaotic mapping and Gaussian mutation to help the algorithm escape local optima. The hyperparameter search was performed on a distinct validation set to prevent information leakage. The fitness function for the optimization process is often the Mean Absolute Error (MAE). The core update rules for the sparrow algorithm are given by the following equations:
For the producer’s location update, when R2 < ST:
\[
x_{i,d}^{t+1} = x_{i,d}^{t} \cdot (1 + Q)
\]
For the scrounger (follower) update:
\[
x_{i,d}^{t+1} = xb_{i,d}^{t} + \frac{1}{D} \sum_{d=1}^{D} (rand(-1,1) \cdot xb_{i,d}^{t} – x_{i,d}^{t})
\]
4. Comparative Analysis of Prediction Methods
4.1 Performance of Ensemble Learning Algorithms
I first evaluated the performance of several ensemble learning algorithms on the Severson dataset. The task was to predict the current cycle number of the EV battery pack based on the charge/discharge characteristics. The dataset was shuffled and split into a 9:1 ratio for training and testing. The results from these experiments are shown in Table 4.1.
Table 4.1: Performance Metrics for Different Models
| Model | MAE | MSE | Pred > 20% | 10% < Pred < 20% | Pred < 10% |
| :— | :— | :— | :— | :— | :— |
| Random Forest| 22.20 | 3375.61 | 10.75% | 7.94% | 81.31% |
| XGBoost | 27.66 | 3447.43 | 12.89% | 11.00% | 76.11% |
| LightGBM | 31.53 | 3933.45 | 15.30% | 12.98% | 71.72% |
| CatBoost | 25.43 | 2926.77 | 11.87% | 11.04% | 77.10% |
My analysis showed that Random Forest performed best in terms of MAE for this initial dataset, with a value of 22.20, and also had the highest percentage of predictions with less than 10% error. While LightGBM had the highest MAE, it demonstrated lower relative errors for the points where its predictions deviated by more than 20%, indicating better stability. However, after a deeper analysis, we observed that the error was disproportionately high for data points where the true cycle number was very low (between 1 and 10 cycles). Excluding these early-life data points to focus on the operational lifecycle of the EV battery pack resulted in improved metrics across all models.
Table 4.2: Model Performance After Filtering Low-Cycle Data
| Model | MAE | MSE | Pred > 20% | 10% < Pred < 20% | Pred < 10% |
| :— | :— | :— | :— | :— | :— |
| Random Forest| 21.81 | 3354.76 | 6.7% | 7.15% | 86.14% |
| CatBoost | 25.33 | 2957.23 | 6.77% | 10.32% | 82.90% |
| XGBoost | 27.60 | 3490.52 | 7.81% | 10.44% | 81.75% |
| LightGBM | 31.50 | 3985.01 | 9.59% | 12.92% | 77.5% |
Based on these results, I sought to further improve the CatBoost model by augmenting the input feature set. I compared the use of a model with six features (adding Tmax) to a model were the least important feature (IR) was replaced by Tmax in a five-feature set. Using six parameters yielded a significantly better MAE of 18.60 and MSE of 1787, reinforcing the initial finding that inputting more useful information into the model for an EV battery pack health prediction is beneficial.
4.2 Performance of Neural Networks
To explore the performance of neural networks and their capacity to handle various data formats, I constructed a custom neural network, as presented in the original thesis, to process 7 features of shape 1×1 alongside 1 feature of shape 1×1000. This approach increases the volume of training data substantially compared to using only simple ensemble methods.
Table 4.3: Prediction Results of Neural Networks and CatBoost
| Model | MSE | MAE |
| :— | :— | :— |
| DNN (Case 1) | 12074.13 | 70.8 |
| DNN+LSTM (Case 2)| 3863.29 | 43.07 |
| CatBoost (Case 3) | 1525.03 | 19.49 |
The results in Table 4.3 illustrate that CatBoost, using just seven 1×1 features, achieved significantly better prediction accuracy compared to both the DNN and the DNN-LSTM hybrid network. This highlights the strength of gradient boosting on structured tabular data. I observed that a critical difference lies in the fact that neural networks may suffer from producing negative predictions. However, the main advantage of neural networks is their flexibility in handling sequential or unstructured data, which is common in the battery management field when analyzing EV battery pack signals.
4.3 Performance of Bayesian Probability Models
I investigated the application of the Hidden Markov Model (HMM) as an example of a Bayesian probability model. HMM can be applied in both supervised and unsupervised learning settings. In the unsupervised approach, I treated the battery parameters as observations and attempted to predict the next state. While it does not rely on a direct mapping with distinct numerical outputs for the cycle number, it can be used in sequence modeling. Using a supervised approach, I discretized the parameters and outputs into classes and trained the HMM to predict the array of these classes. While the results fell short of what was achieved with neural networks and CatBoost, the supervised HMM model showed predictive promise on the EV battery pack dataset, with low prediction errors on the transformed data.
5. Development of A Hybrid Model for Enhanced Prediction
5.1 Model Architecture
Recognizing the unique strengths of the CatBoost algorithm for structured data and the LSTM for its sequential processing capacity, I orchestrated a hybrid fusion model, drawing inspiration from Stacking techniques. The architecture is as follows:
1. **Base Neural Network:** The 7 features (1×1) are first fed into a multi-layer DNN to generate a set of intermediate features. In parallel, the single 1×1000 time-series feature is fed into an LSTM layer.
2. **Feature Extraction:** The ultimate layer of the DNN-LSTM network contains 8 neurons before the output layer. I intentionally extracted the input to this final layer, which comprises 8 features. These extracted features can be considered as a learned, abstract representation of the input data.
The extracted features were then concatenated with the original set of 7 features to form a new training and testing dataset for the final CatBoost model. The structure of the fusion model, which combines the neural network and CatBoost, is designed to harness the predictive power of gradient boosting while supplying it with richer, learned features.
Table 5.1: Hyperparameters for the CatBoost Model
| Algorithm | Hyperparameter | Value |
| :— | :— | :— |
| CatBoost | iterations | 12000 |
| | depth | 12 |
| | learning_rate | 0.02 |
| | bagging_temperature | 0.2 |
| | random_seed | 23 |
5.2 Fusion Model Results
The introduction of these 8 extra features significantly improved the prediction performance of the CatBoost model. The comparison between the original CatBoost model (Case 3) and the new fusion model is presented in Table 5.2.
Table 5.2: Prediction Performance of the Fusion Model on Test Set
| Model | MSE | MAE | Relative Error < 5% |
| :— | :— | :— | :— |
| CatBoost (Case 3) | 1525.03 | 19.49 | – |
| Fusion Model | 641.44 | 11.5 | 78.85% |
The fusion model decreased the MAE by roughly 41% (from 19.49 to 11.5) compared to the single CatBoost model. This suggests that the improved representation learned by the neural network aids the boosting trees in making more precise splits. To further confirm that the extracted features were meaningful and not a source of noise, I conducted an ablation test (Case 4). I replaced the 8 extracted features with 8 random arrays and re-ran the CatBoost model. The test results show a drop in accuracy on the testing set, confirming that the neural network’s output features carry meaningful, valuable predictive information for the EV battery pack health prediction.
6. Analyzing the Genesis and Universality of the Fusion Model
6.1 Validation on Additional Datasets
To guarantee the universality of the fusion model, I applied the same logic to the NASA and Oxford datasets, which contain different types of battery measurements. For the NASA dataset, the goal is to predict the battery’s cycle number using impedance-related features, and for the Oxford dataset, using cycling profiles.
Table 6.1: Comparison of Models on NASA and Oxford Datasets
| Dataset | Model | MAE | MSE | Test Mean |
| :— | :— | :— | :— | :— |
| NASA | DNN | 20.82 | 800.72 | 92.25 |
| | CatBoost | 17.77 | 730.81 | 92.25 |
| | Fusion Model | 9.49 | 162.65 | 92.25 |
| Oxford | CatBoost | 140.50 | 64814.20 | 3528.85 |
| | Fusion Model | 138.36 | 33783.78 | 3528.85 |
The results demonstrate that the fusion model also outperformed the standalone models on these completely different datasets, confirming its general superior performance for this kind of task.
6.2 Feature Extraction and Data Quality
The reason the fusion model works well could be due to data quality: While the original features might be the raw inputs, the extracted features represent the network’s attempt to transform these inputs into a structure that makes it easier for CatBoost to fit. The neural network (function f) learns complex patterns and extracts high-level features. The success of the fusion model, even when the extracted features do not add strictly new types of raw data, suggests that the distribution of the data is transformed into a more distinct representation, thus benefiting the classifier or regressor. The process of predicting the health of an EV battery pack using this method effectively combines the strengths of deep learning and gradient boosted trees.
7. Conclusion and Outlook
Thorough my research, I have drawn the following key conclusions:
1. **Methodology:** For the prediction of EV battery pack health information, the process hinges not only on the algorithm choice but also heavily on data preprocessing and feature engineering. My evaluation shows that parameters like the maximum discharge power and the maximum temperature inside the battery pack have high importance but that this importance varies with the feature cohort.
2. **Algorithm Choice:** For numerical, tabular datasets representing an EV battery pack, gradient boosted decision trees like CatBoost offer an excellent combination of ease of use and high predictive accuracy. While providing the highest accuracy, neural networks offer the flexibility to process time series data directly but require longer training durations.
3. **Fusion Model:** The proposed DNN-LSTM-CatBoost fusion model provides an effective architecture to combine these two strengths. By converting high-dimensional time-series data into a lower-dimensional intermediary representation, it allows the CatBoost algorithm to gain enhanced predictive insights, resulting in a 41% reduction in MAE compared to the original CatBoost model and substantial performance leaps on the supplementary datasets.
Future work should focus on validating this approach against different machine learning frameworks beyond CatBoost, such as Support Vector Machines (SVM), while also exploring other state-of-the-art sequence learning architectures to further improve the accuracy and robustness of the EV battery pack health assessment.